


Conversational AI & Copilots
Interactive assistants tailored to internal tools, support workflows, or system docs.
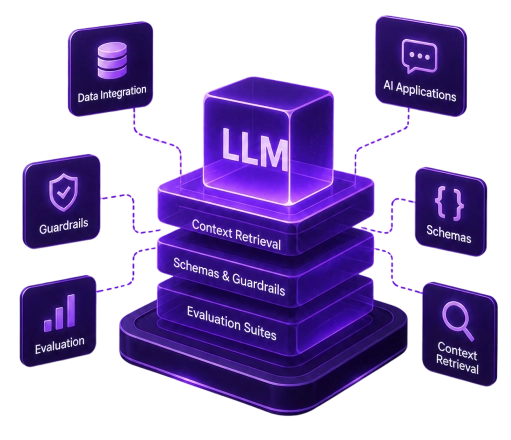
Build, integrate, and scale production LLM Applications with context retrieval, guaranteed schemas, guardrails, and evaluation suites.
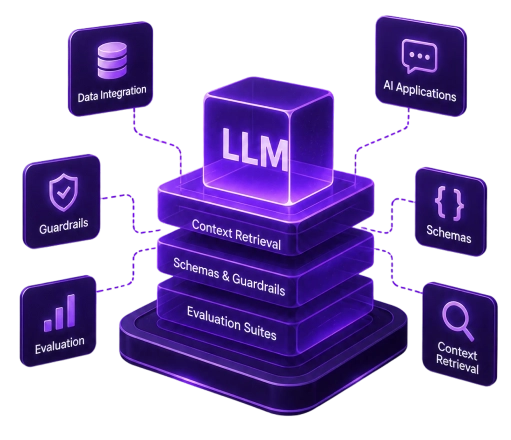
Key pillars that transform foundation models into reliable enterprise applications.
Enforce JSON Schema and Pydantic models for predictable, runtime-safe software integration.
Dynamic context retrieval via RAG across vector databases, SQL stores, and internal APIs.
Input sanitization, output filtering, and PII masking built directly into execution flows.
Continuous tracing and token monitoring to optimize expenditure and response times.
Unmanaged prompt chains cause production risks—software wrappers turn raw outputs into reliable microservices.
Unstructured model responses break downstream API code.
Models assert ungrounded false facts without retrieval verification.
Unoptimized prompt context consumes excess budget and increases lag.
Convert unpredictable outputs into strictly validated JSON schemas.
Fetch live corporate facts directly into the prompt context window.
Track execution paths, token counts, and accuracy metrics in production.
Foundational enterprise LLM application patterns engineered for production scale.
Interactive assistants tailored to internal tools, support workflows, or system docs.
Extraction, classification, and summarization across unstructured PDFs and contracts.
Hybrid vector and keyword retrieval engines over distributed knowledge bases.
Safely translating natural language questions into executable database queries.
Extracting structured intent to invoke external APIs and automate complex business tasks.
Architectural strategies aligned with your latency, privacy, and accuracy needs.
Ideal for single-step text transformations, data extraction, or basic classification where no external context is needed.
Essential for dynamic knowledge, real-time document citations, and eliminating hallucinations through retrieval.
Best for high-throughput, domain-specific tasks needing low latency, consistent behavior, and fixed output formats.
Continuous tracing, token cost optimization, and input/output filtering across all your LLM endpoints.
Architect, scale, and secure your production LLM Applications today.
Explore production architectural patterns and real-time execution benchmarks.
Architect custom LLM software over your data and infrastructure.
Evaluate your AI software stack with senior AI systems architects.
Essential insights into production LLM Application development.
Explore more AI capabilities that transform your business.