


Up to 60% Cost Reduction
Spot instances, mixed-precision, and auto-scaling dramatically lower GPU spend.
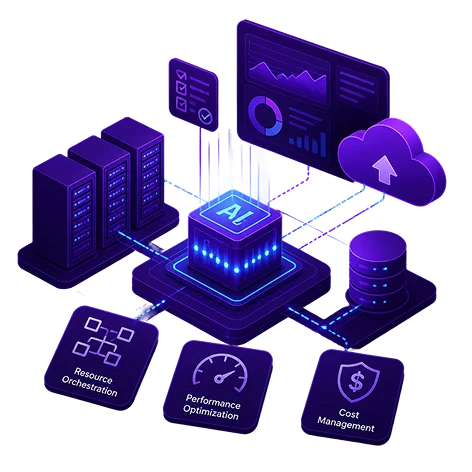
High-performance GPU orchestration and cost reduction to maximize ROI without burning capital.
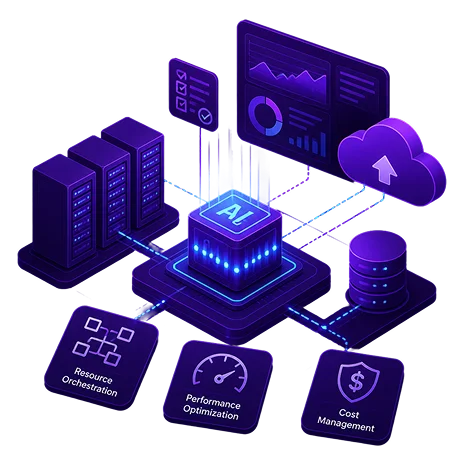
Smart compute orchestration across GPU, TPU, and edge hardware.
Kubernetes & Ray resource allocation for optimized training and batching.
Spot instances, quantization, and auto-scaling to cut compute spend up to 60%.
Distributed edge/cloud setups built for fast bandwidth and low network latency.
Unified GPU pooling across AWS, GCP, and Azure for maximum resilience.
Measurable results from optimized AI infrastructure.
Spot instances, mixed-precision, and auto-scaling dramatically lower GPU spend.
Horizontal pod autoscalers handle traffic spikes without model degradation.
Parallel job scheduling and batch optimization accelerate model training cycles.
Seamless inference serving from edge devices to centralized GPU clusters.
Without intelligent resource management, AI infrastructure becomes the biggest expense — and the biggest bottleneck.
"Smart infrastructure turns GPU spend from a cost center into a competitive advantage."
Choose the right orchestration strategy for your scale and compliance needs.
Industry-standard orchestration for ML pipelines with GPU scheduling, distributed training, and model serving on managed Kubernetes.
Distributed computing framework for massive-scale data processing and model training, seamlessly scaling from laptops to multi-node clusters.
Purpose-built AI hardware clusters with NVLink interconnects, Slurm or Kubernetes orchestration for maximum data privacy and throughput.
Quick insights into AI Infrastructure & Resource Management.
Explore more AI capabilities that transform your business.